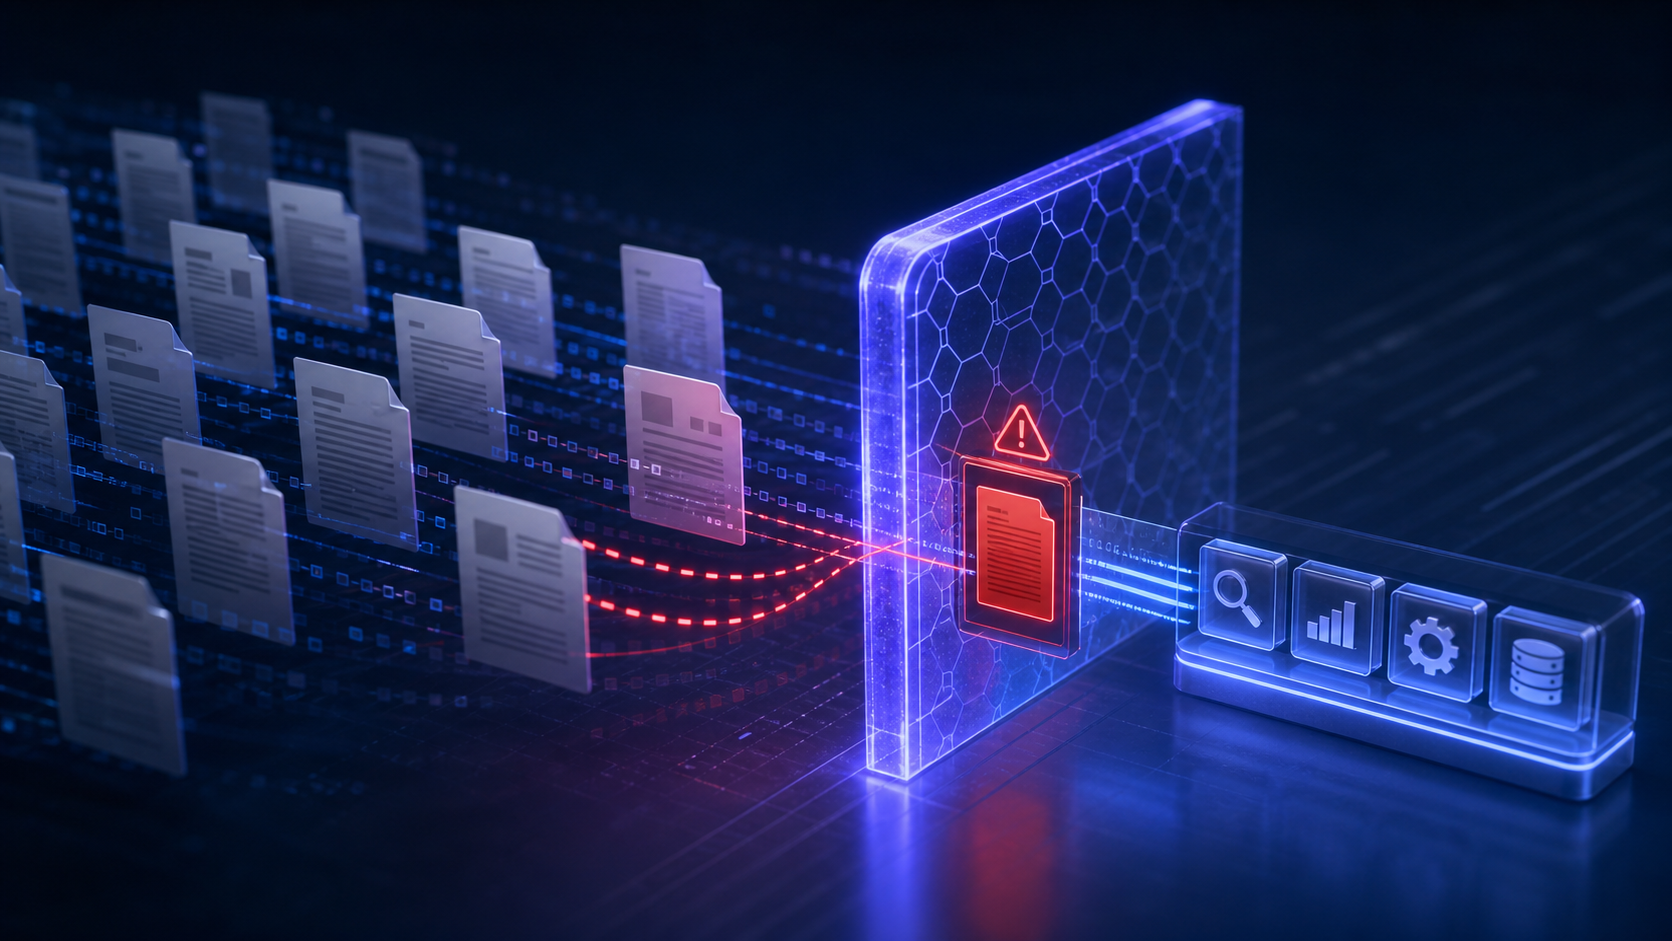
An AI assistant may be asked to summarize a webpage, read an email or inspect a document. That material is supposed to be data. If it contains language telling the assistant to ignore its task or reveal information, the model may interpret the text as an instruction. This is prompt injection.
Direct and indirect attacks
A direct injection comes from the person using the system. They deliberately write instructions designed to override the application’s rules.
An indirect injection is hidden inside content the system retrieves: a webpage, file, calendar event or message. The user may never see the malicious text. This becomes more serious when an AI agent can send email, change records or call external tools.
Prompt injection is not identical to traditional code injection. The model is responding to natural language rather than executing the text as software. The security problem comes from an unreliable boundary between trusted instructions and untrusted content.
Why a warning in the prompt is not enough
Developers often tell a model to ignore malicious instructions. That can help, but it does not create a dependable security boundary. Attackers can rephrase requests, hide them in long content or exploit conflicts the application did not anticipate.
Input filters face the same limitation. Ordinary documents contain phrases that look like instructions, and harmful text can be disguised. Blocking every suspicious phrase would also block legitimate information.
Reduce what an attack can accomplish
The strongest protection is to limit consequences even when the model makes a mistake.
- Give the system only the permissions required for the current task.
- Separate reading from acting whenever possible.
- Require human confirmation before sending, purchasing, deleting or publishing.
- Restrict which tools and destinations the assistant may use.
- Treat retrieved webpages and documents as untrusted input.
- Keep secrets out of prompts and tool results when the model does not need them.
- Record actions so unusual behavior can be reviewed.
Structured interfaces also help. Instead of letting a model invent any command, an application can require a defined action with validated fields.
What users can do
Be cautious when an assistant asks for new permissions after reading outside content. Review a generated message before it is sent, and verify changes in the original application. For sensitive work, avoid connecting broad accounts when a read-only or limited account will do.
Prompt injection remains an active security problem. A safe design assumes the model may sometimes follow the wrong instruction and builds controls around that possibility. The goal is not merely to detect every clever phrase; it is to prevent one misleading document from gaining real authority.
Sources
- NIST, Generative AI Profile: https://doi.org/10.6028/NIST.AI.600-1
- OWASP, Prompt Injection Prevention Cheat Sheet: https://cheatsheetseries.owasp.org/cheatsheets/LLM_Prompt_Injection_Prevention_Cheat_Sheet.html