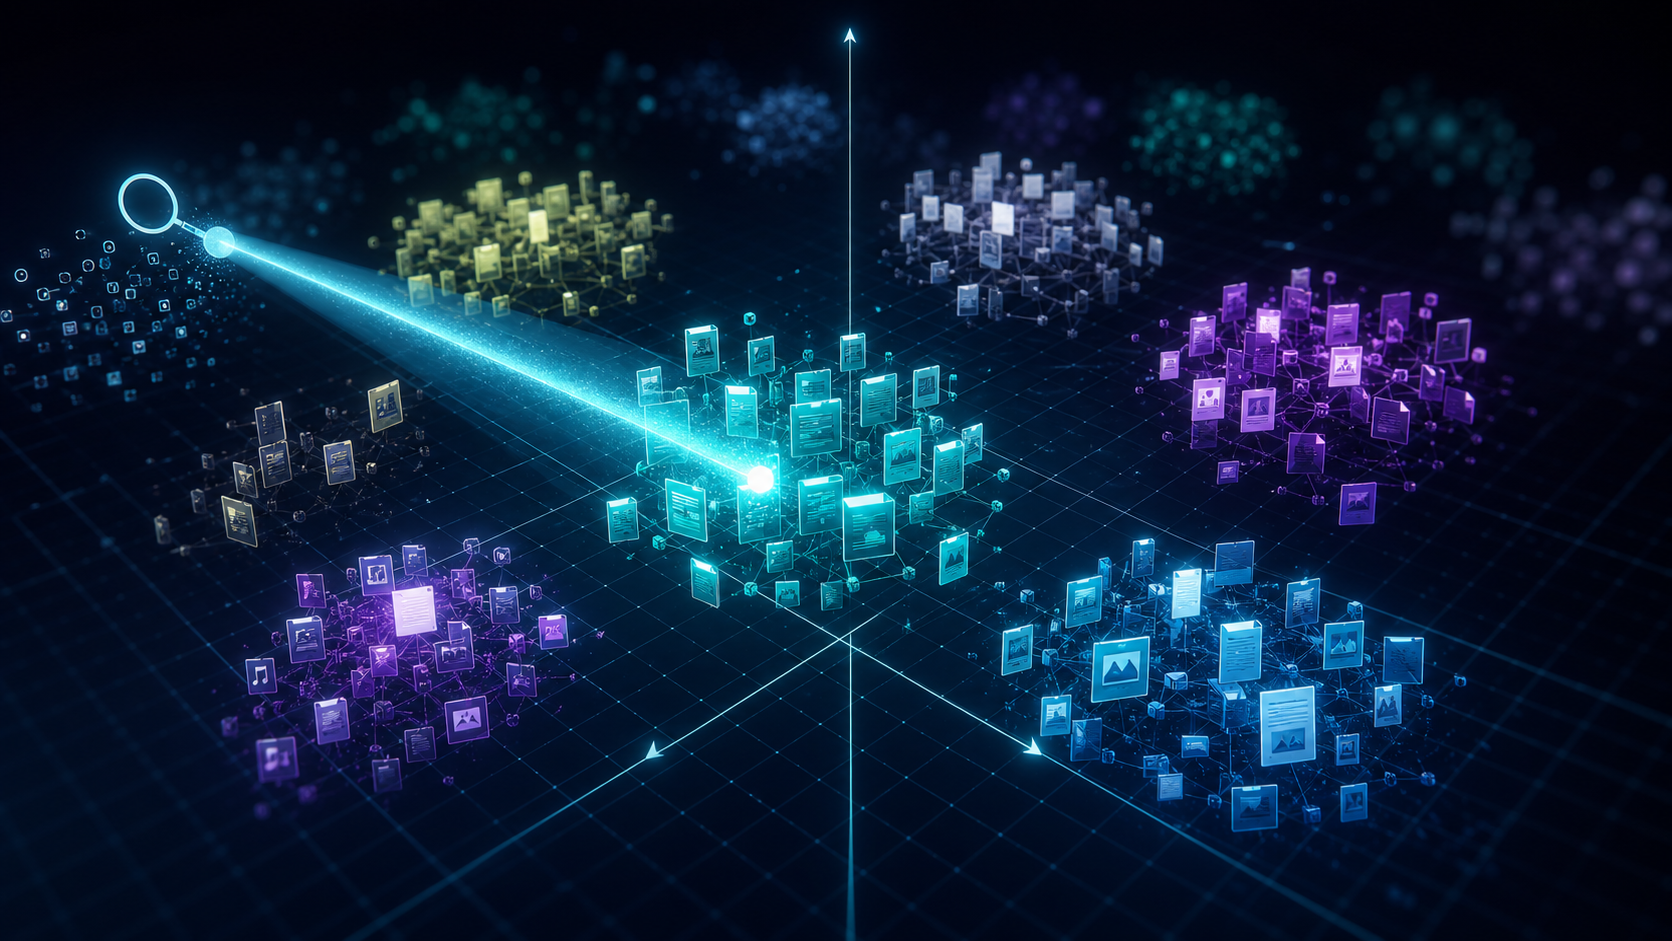
A traditional keyword search looks for matching words. An embedding-based system tries to find items with related meaning, even when they use different language. That difference powers many recommendation tools, document search systems and AI retrieval features.
From an item to a vector
An embedding model converts a piece of data into a vector: an ordered list of numbers. The list is not a readable summary. Instead, its position in a mathematical space reflects patterns the model learned during training.
Items with similar meaning tend to be closer together. A search for “how to improve laptop battery life” might therefore retrieve a document titled “ways to extend notebook runtime,” despite the lack of exact wording.
Embeddings can represent sentences, documents, images, products or users. The model and the application determine what kind of similarity the numbers capture.
How semantic search works
First, a system divides its documents into useful sections. It creates an embedding for each section and stores the vectors in an index. When a person submits a question, the same embedding model converts that question into another vector.
The system compares the query vector with stored vectors and returns the nearest matches. An AI assistant may then use those passages to compose an answer, often through retrieval-augmented generation.
The quality of the result depends on more than the embedding model. Document structure, section size, metadata, filters and ranking rules all matter.
Similarity is not proof
A nearby vector means the model found a pattern of similarity. It does not guarantee that the result is correct, current or appropriate.
For example, two medical documents may discuss the same condition while recommending different treatments. Their semantic similarity does not resolve which guidance applies. Dates, authorship and other metadata still need to be checked.
Embeddings can also reflect weaknesses in their training data. Specialized vocabulary, uncommon languages and ambiguous phrases may be represented less reliably.
Privacy and maintenance
Vectors may look like anonymous numbers, but organizations should not automatically treat them as harmless. Research has shown that information can sometimes be inferred from embeddings. Access controls, retention rules and deletion procedures should cover both the original documents and derived indexes.
Indexes also need updating. A perfect match to an obsolete policy is still an obsolete result.
When embeddings are useful
They are a strong fit when people describe the same idea in different words: support archives, product discovery, knowledge bases and duplicate detection. Exact search remains better for serial numbers, legal citations or a specific error code.
The best search systems often combine both approaches. Keywords preserve precision, while embeddings add flexibility. Understanding that tradeoff makes semantic search easier to evaluate—and harder to mistake for genuine comprehension.
Sources
- Sentence-BERT research paper: https://arxiv.org/abs/1908.10084
- NIST, AI Risk Management Framework: https://www.nist.gov/itl/ai-risk-management-framework